VLA for Sidewalk Robot (COCO)
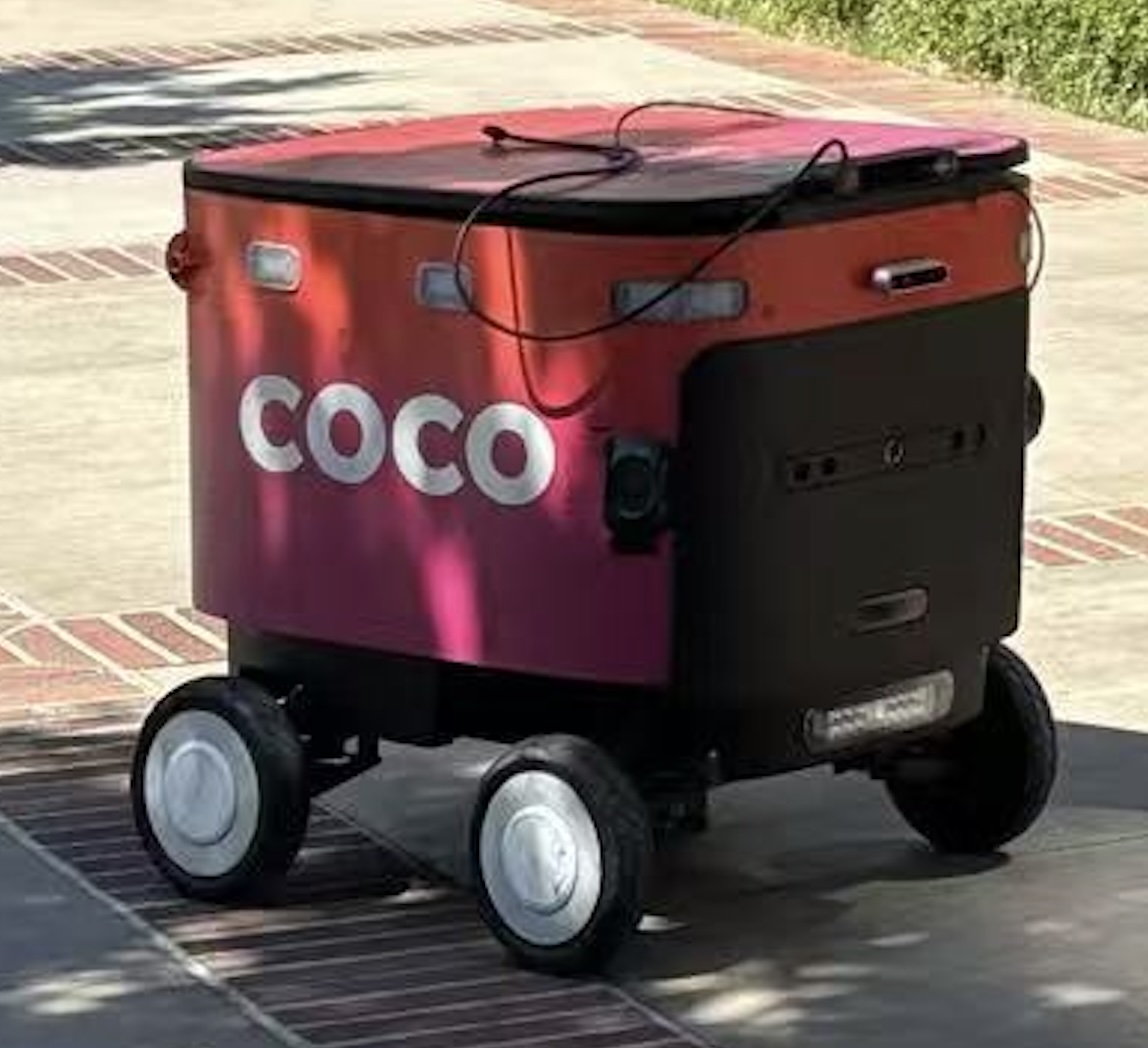
Research on enabling more intelligent driving for COCO, a sidewalk delivery robot, by building a Vision-Language-Action (VLA) policy that grounds camera observations and language instructions directly into navigation actions. The policy is refined with reinforcement learning (RL) and real-world driving data so the robot can handle crowded sidewalks, crossings, and unexpected obstacles in urban delivery environments.